Prompt caching for large-scale prompting
When you keep repeating the same context or instructions across queries, prompt caching cuts cost and latency by reusing the static parts.
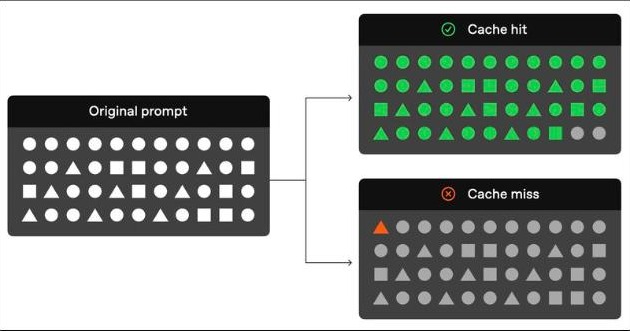
Prompt caching is such a useful feature when working on large-scale direct prompting tasks in industry. In most cases, we often find ourselves repeating the same context or instructions across a wide set of queries or documents. This repetition leads to higher inference costs and slower response times when using isolated inference calls.
Prompt caching helps a lot here by letting us cache and reuse those static parts. It reduces costs (cached tokens are up to 50% cheaper) and improves performance with a faster Time to First Token.
Definitely something worth looking into if you’re doing repeated prompting at scale.